Multi-Platform Weekly Performance Index Feasibility Study: Honest Kill of the Headline Acquisition-Cost Metric
Finish the feasibility study with an honest publish/don't-publish verdict for every metric on the proposed scorecard, before any number ships to anyone.
What was getting in the way.
"Give us one weekly scorecard that compares all our ad platforms" is a universally-asked and universally-botched request. The honest answer is almost always "the metric you want doesn't exist in these exports", but very few scorecards get killed before publication. More commonly, a composite number ships, somebody notices it doesn't tie to any source, and the dashboard loses trust forever.
Context
Universal: applies wherever an AI agent is asked to compose a composite metric from exports whose definitions don't line up.
How the work runs.
- 01
Trigger
a stakeholder asks for a weekly cross-platform performance index.
- 02
Inventory the sources
catalog every platform export's schemas, coverage, dedupe rules, currency handling, and restatement behavior, not just what columns exist, but how they're calculated.
- 03
Prototype the week-over-week pass
build a working prototype of the whole pipeline; every scan is dry-run costed before execution so the feasibility study doesn't itself cost production dollars.
- 04
Grade each metric for cross-platform honesty
for every proposed metric, state whether it exists in every export, whether the denominators are comparable, and whether any single platform's definition would silently dominate the composite.
- 05
Kill what can't be honest
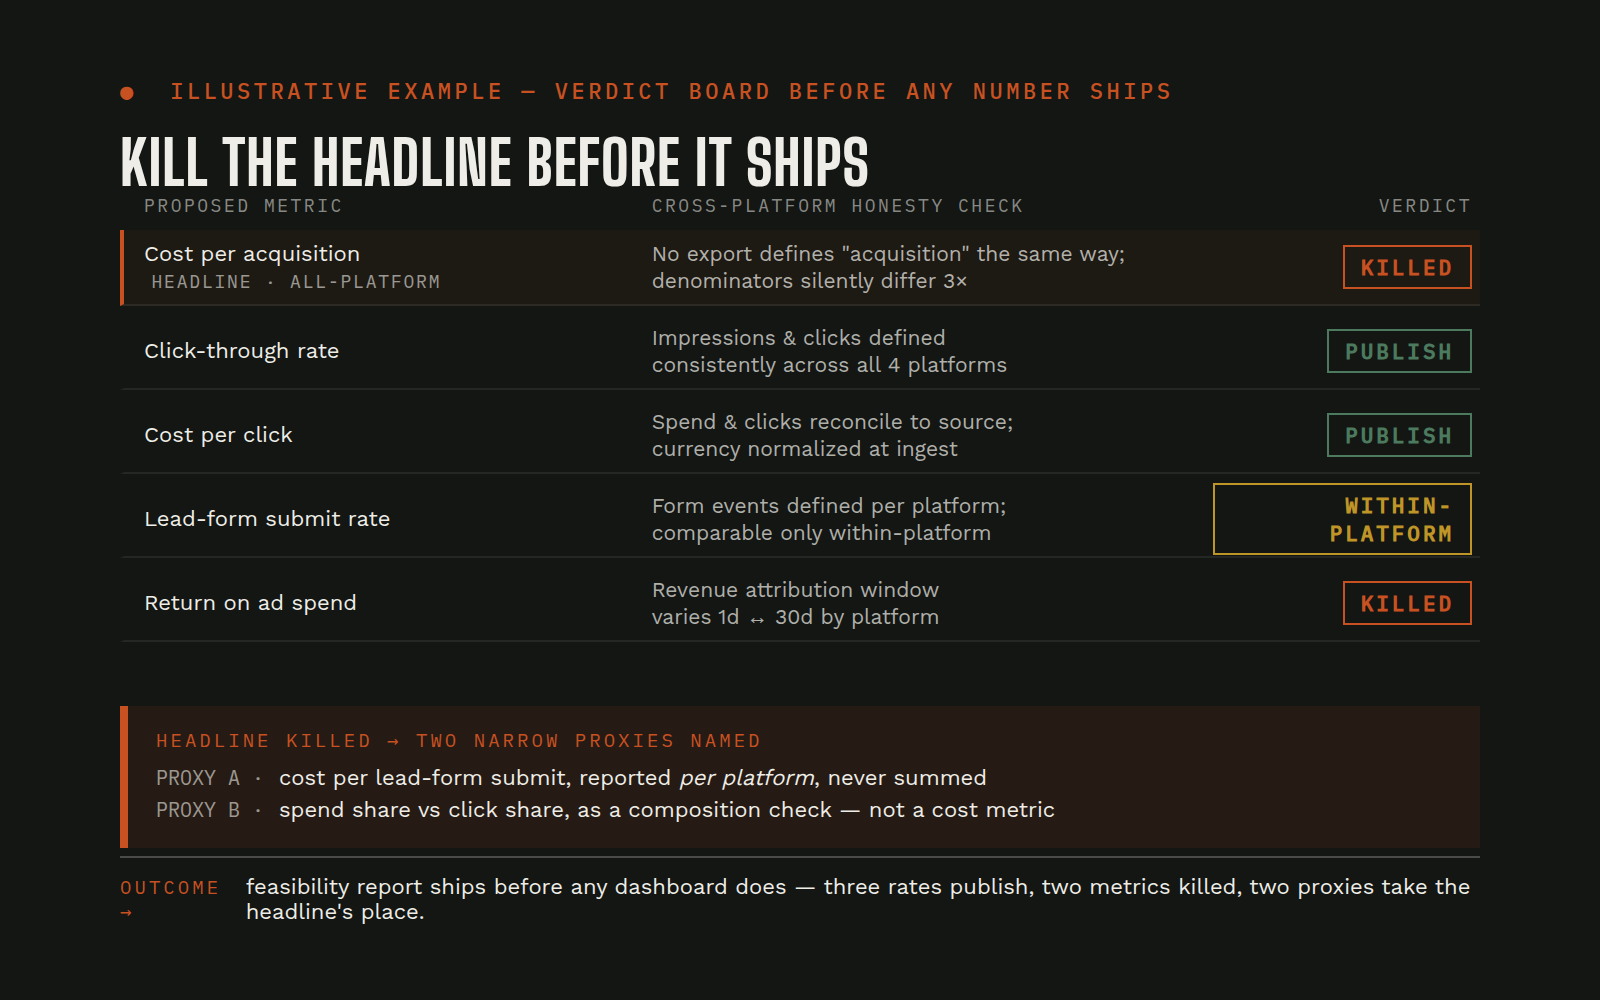
say so publicly before anyone publishes, including the headline metric everyone wanted, and name the narrow proxies that can be published honestly in its place.
- 06
Outcome
a feasibility report with a short list of publishable metrics, a short list of killed ones, and the proxies that take the dead headline's place.
Evidence from the workflow.
Each system has a role.
Intake
Ad platform APIs (search / social / shopping / etc.)
Action (prototype)
Data warehouse
Signal (budget guard)
Scheduled dry-run cost estimator
Why this is Operator.
Owns a workflow end to end, running the process inside the authority you set.
- 01
Feasibility study output is advisory; no production dashboard is published from a study that killed its own headline. Every kill call is accompanied by the exact test that failed, so a future stakeholder can re-run it against new data without re-opening the whole study.
Impact / Outcomes
Three rate metrics qualified as cross-platform publishable across all four platforms in scope.
The headline acquisition-cost metric everyone wanted exists in no platform export, killed in the feasibility report before any dashboard shipped.
Two narrow proxies named as defensible substitutes, with the limits of each stated in writing.
Prototype's scans were every dry-run costed before execution, zero surprise cloud bills from the feasibility work itself.
Find where a workflow like this fits.
Start with the systems, work, constraints, and authority already present in your operation.